Page MenuHomePhabricator

Kubernetes apiserver probe failures on restart
Closed, ResolvedPublic

Description

Last night we got paged for probe failures for Kubernetes apiserver in codfw:

01:35:41 <jinxer-wm> (ProbeDown) firing: (2) Service kubemaster2001:6443 has failed probes (http_codfw_kube_apiserver_ip4) #page - https://wikitech.wikimedia.org/wiki/Runbook#kubemaster2001:6443 - https://grafana.wikimedia.org/d/O0nHhdhnz/network-probes-overview?var-job=probes/custom&var-module=All - https://alerts.wikimedia.org/?q=alertname%3DProbeDown

It turns out the apiserver on kubemaster2001 restarted at 00:53, and again at 01:33:

Mar 01 00:53:35 kubemaster2001 systemd[1]: kube-apiserver.service: Succeeded.
Mar 01 00:53:35 kubemaster2001 systemd[1]: Stopped Kubernetes API Server.
Mar 01 00:53:35 kubemaster2001 systemd[1]: kube-apiserver.service: Consumed 1w 4d 11h 55min 22.441s CPU time.
Mar 01 00:53:35 kubemaster2001 systemd[1]: Starting Kubernetes API Server...

The same happened on kubemaster2002 at 00:52, and again at 01:34.

We lost probes on both hosts both times, but it only paged the second time: https://grafana.wikimedia.org/goto/_YP4RkASz?orgId=1

It shows up in the resource graphs: https://grafana.wikimedia.org/goto/by8I-qTSz?orgId=1

@Clement_Goubert identified this as a Puppet cert renewal, which makes sense: https://puppetboard.wikimedia.org/report/kubemaster2001.codfw.wmnet/5a536b70ffe6b5d7b7d0c62ddde739b101a4bc25 But Puppet ran on kubemaster2001 at 00:51, and on kubemaster2002 at 01:31, so it looks like we restarted both servers both times -- that might be an effect of coordinating a rolling restart to minimize leader elections, but doing the rolling restart twice might be a bug; I haven't dug into it yet.

So, questions:

  • Is the 2x2 restart expected?
  • Of course starting up the apiserver is expensive. Is it expected to lock up for so long that probes fail?
    • If not, should we do something about that?
    • If so, should we bump the alert thresholds so it doesn't page?
  • Did the rolling restart succeed in avoiding any actual API unavailability (because the elected leader was always serving)?
    • If so, nothing was actually wrong -- should we only alert on the API service, and not on individual machines?
Event Timeline

RLazarus triaged this task as Medium priority.
RLazarus renamed this task from Kubernetes apiserver probe failures on resatrt to Kubernetes apiserver probe failures on restart.Mar 4 2024, 5:07 PM

To clarify why this happened/happens:
kubemaster2001 refreshed the certs used by the apiserver in one puppet run at ~00:51:

Mar  1 00:51:28 Exec[renew certificate - wikikube__kube-apiserver_server]) Scheduling refresh of Service[kube-apiserver-safe-restart]
Mar  1 00:51:28 Exec[renew certificate - wikikube__kube-apiserver_server]) Scheduling refresh of Service[kube-controller-manager]
Mar  1 00:51:28 Exec[renew certificate - wikikube__kube-apiserver_server]) Scheduling refresh of Service[kube-scheduler]
Mar  1 00:51:29 Exec[renew certificate - wikikube__sa_service-account-management]) Scheduling refresh of Service[kube-apiserver-safe-restart]
Mar  1 00:51:29 Exec[renew certificate - wikikube__sa_service-account-management]) Scheduling refresh of Service[kube-publish-sa-cert]
Mar  1 00:51:30 Exec[renew certificate - wikikube__kube-apiserver-kubelet-client]) Scheduling refresh of Service[kube-apiserver-safe-restart]
Mar  1 00:51:31 Exec[renew certificate - wikikube_front_proxy__front-proxy-client]) Scheduling refresh of Service[kube-apiserver-safe-restart]
Mar  1 00:51:31 Exec[renew certificate - wikikube__system_kube-scheduler]) Scheduling refresh of Service[kube-scheduler]
Mar  1 00:51:32 Exec[renew certificate - wikikube__system_kube-controller-manager]) Scheduling refresh of Service[kube-controller-manager]
Mar  1 00:51:34 Exec[renew certificate - wikikube__kubelet_server]) Scheduling refresh of Service[kubelet]
Mar  1 00:51:34 Exec[renew certificate - wikikube__system_node_kubemaster2001_codfw_wmnet]) Scheduling refresh of Service[kubelet]
Mar  1 00:51:35 Exec[renew certificate - wikikube__system_kube-proxy]) Scheduling refresh of Service[kube-proxy]

This also refreshed the wikikube__sa_service-account-management cert which triggers kube-publish-sa-cert to publish the new certificate to etcd for all other apiservers to consume (all apiservers need the public key of all other apiservers sa-cert to validate service account tokens issues by other apiservers - T329826), leading to a apiserver restart on both masters:

Mar 01 00:51:36 kubemaster2001 systemd[1]: Starting Restart kube-apiserver using a etcd lock... <- read "Trying to acquire lock to restart kube-apiserver"
Mar 01 00:53:35 kubemaster2001 systemd[1]: Stopped Kubernetes API Server.
Mar 01 00:53:35 kubemaster2001 systemd[1]: Starting Kubernetes API Server...
Mar 01 00:53:39 kubemaster2001 systemd[1]: Started Kubernetes API Server.
Mar 01 00:53:39 kubemaster2001 systemd[1]: Finished Restart kube-apiserver using a etcd lock.
Mar 01 00:51:30 kubemaster2002 systemd[1]: Starting Restart kube-apiserver using a etcd lock... <- read "Trying to acquire lock to restart kube-apiserver"
Mar 01 00:52:31 kubemaster2002 systemd[1]: Stopped Kubernetes API Server.
Mar 01 00:52:31 kubemaster2002 systemd[1]: Starting Kubernetes API Server...
Mar 01 00:52:35 kubemaster2002 systemd[1]: Started Kubernetes API Server.
Mar 01 00:52:35 kubemaster2002 systemd[1]: Finished Restart kube-apiserver using a etcd lock.

The same thing then happens the other way around at ~01:32 when kubemaster2002 refreshes certs.

Mar 01 01:32:48 kubemaster2001 systemd[1]: Starting Restart kube-apiserver using a etcd lock..
Mar 01 01:33:49 kubemaster2001 systemd[1]: Stopped Kubernetes API Server.
Mar 01 01:33:49 kubemaster2001 systemd[1]: Starting Kubernetes API Server...
Mar 01 01:33:52 kubemaster2001 kube-apiserver[2750643]: I0301 01:33:52.534043 2750643 secure_serving.go:266] Serving securely on [::]:6443
Mar 01 01:33:52 kubemaster2001 systemd[1]: Started Kubernetes API Server.
Mar 01 01:33:52 kubemaster2001 systemd[1]: Finished Restart kube-apiserver using a etcd lock
Mar 01 01:32:52 kubemaster2002 systemd[1]: Starting Restart kube-apiserver using a etcd lock...
Mar 01 01:34:52 kubemaster2002 systemd[1]: Stopped Kubernetes API Server.
Mar 01 01:34:52 kubemaster2002 systemd[1]: Starting Kubernetes API Server...
Mar 01 01:34:56 kubemaster2002 kube-apiserver[2502595]: I0301 01:34:56.946822 2502595 secure_serving.go:266] Serving securely on [::]:6443
Mar 01 01:34:56 kubemaster2002 systemd[1]: Started Kubernetes API Server.
Mar 01 01:34:56 kubemaster2002 systemd[1]: Finished Restart kube-apiserver using a etcd lock.

kube-apiserver uses sd_notify to notify systemd of it's successful startup, so the etcd lock is only freed after that notification which is why I'm pretty sure there always was a working apiserver - which I unfortunately can't prove retroactively.

On kubemaster2001 something went sideways during the second restart, causing a timeout returning a GET request for the /readyz endpoint (which is what the custom probe that paged is calling):

Mar 01 01:34:47 kubemaster2001 kube-apiserver[2750643]: {"level":"warn","ts":"2024-03-01T01:34:47.675Z","logger":"etcd-client","caller":"v3/retry_interceptor.go:62","msg":"retrying of unary invoker failed","target":"etcd-endpoints://0xc001dbf180/#initially=[https://kubetcd2004.codfw.wmnet:2379;https://kubetcd2005.codfw.wmnet:2379;https://kubetcd>
Mar 01 01:34:47 kubemaster2001 kube-apiserver[2750643]: E0301 01:34:47.675916 2750643 timeout.go:141] post-timeout activity - time-elapsed: 757.350066ms, GET "/readyz" result: Header called after Handler finished
...imagine a fancy go traceback here...

I would assume that this additional failed probe is what kicked the probe other the threshold and led to the page.
(Slower startup should get better with T353464: Migrate wikikube control planes to hardware nodes)

This happened today as well, at 00:35 UTC, when we were paged for this:

00:35:41 <+jinxer-wm> (ProbeDown) firing: Service kubemaster2001:6443 has failed probes (http_codfw_kube_apiserver_ip4) #page - https://wikitech.wikimedia.org/wiki/Runbook#kubemaster2001:6443 -

Resolve:

00:40:41 <+jinxer-wm> (ProbeDown) resolved: Service kubemaster2001:6443 has failed probes (http_codfw_kube_apiserver_ip4) #page - https://wikitech.wikimedia.org/wiki/Runbook#kubemaster2001:6443 -

I got online by the time the resolve had come in (it resolved itself) but it seems like as per this Puppet run and when the service was restarted (~a few mins ago), that this is a repeat of the issue described here.

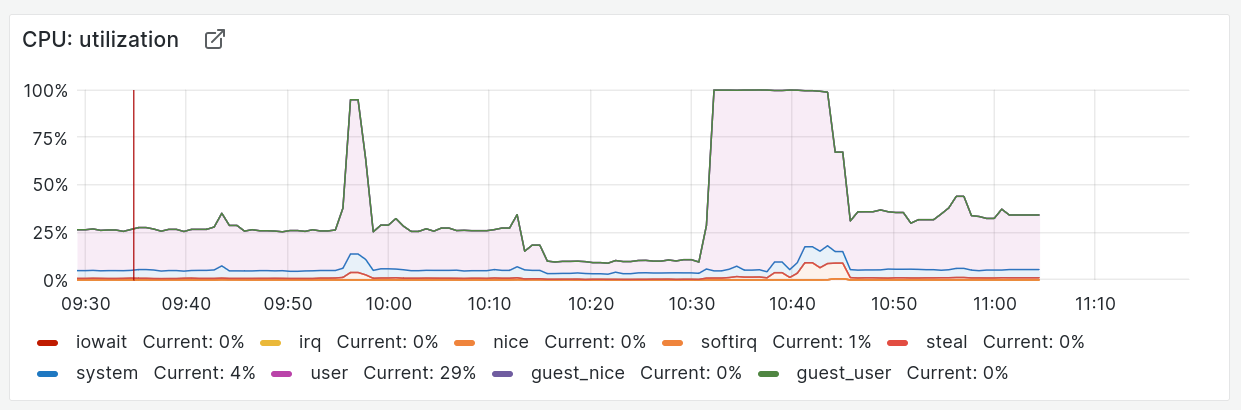
Hi, today we had another occurrence of this. We didn't consider it a full-blown incident due to the no direct (or almost no) impact on users during the service down. After kubemaster1002 was detected as down during its automatic restart (due to a puppet change), it took a long time to come back- with lots of incoming network connections stuck/failing, and maximizing cpu usage. https://grafana.wikimedia.org/goto/KbF5zPaIg?orgId=1

image.png (1,241×410 px, 58 KB)

Probably, as a fallout, miscweb and jobrunner probes also complained:

image.png (2,468×1,118 px, 428 KB)

We had this happening again in eqiad today because of a (planned) apiserver safe restart. We'll prioritize T353464: Migrate wikikube control planes to hardware nodes to give more resources to wikikube apiservers.

akosiaris claimed this task.

Close to 2 years later, and with T353464: Migrate wikikube control planes to hardware nodes done, I don't think we 've seen a recurrence. I 'll boldly resolve